All modalities are equal, but video is more equal: Closing the Cross-Attention Gap in Joint Video Generation
Arxiv
2024
Ohad Rahamim, Dvir Samuel, Idan Schwartz, Gal Chechik

Left: Static 3D mesh input | Right: Animated 4D result
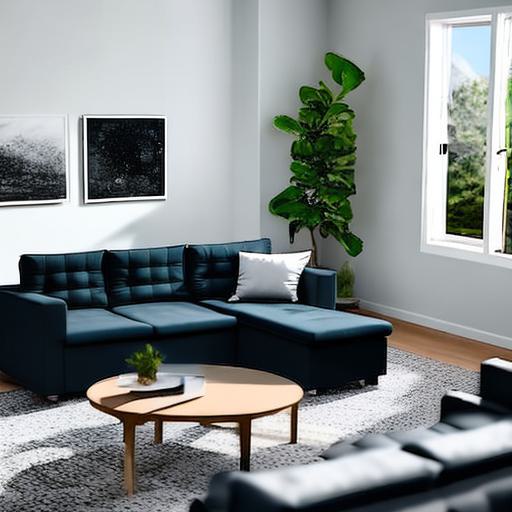
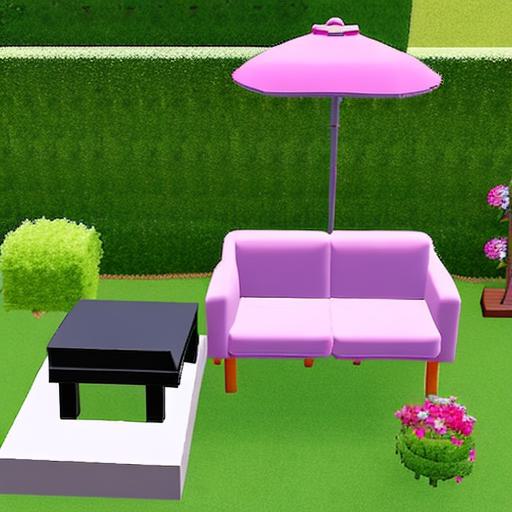
Pair view: 2D Generated layout image (left) vs. 3D Arranged result (right)
Left: Partial input scan | Middle: Completed surface | Right: Completed surface with input points